Hugging Face hosts community model weights that may not appear in Ollama's library. Ollama can download a compatible public GGUF model by its hf.co repository reference and answer prompts locally.
The repository must contain GGUF weights for an architecture supported by Ollama. A quantization tag selects an existing variant of those weights; it does not convert a repository containing only Safetensors files, and no Modelfile is needed for the direct repository method.
Public, ungated repositories require no Hugging Face sign-in. The first download needs internet access, while inference uses the memory and processors of the machine hosting the Ollama service.
Steps to run a Hugging Face model in Ollama:
- List the models already stored in Ollama.
$ ollama list
NAME    ID    SIZE    MODIFIED
Ollama must be installed and its local server running before downloading a model. An empty list has only the header; existing models can remain in place.
Related: How to install Ollama on Linux
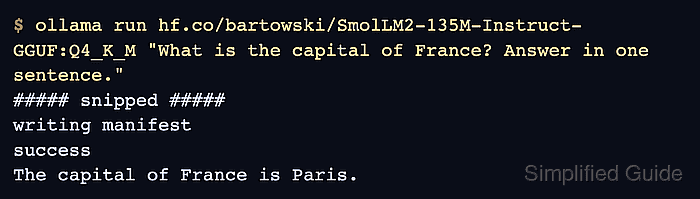
Related: How to check Ollama server status - Run the public SmolLM2 GGUF model with the Q4_K_M quantization. Example output:
$ ollama run hf.co/bartowski/SmolLM2-135M-Instruct-GGUF:Q4_K_M "What is the capital of France? Answer in one sentence."
##### snipped #####
writing manifest
success
The capital of France is Paris.
The SmolLM2-135M-Instruct repository provides this Apache 2.0 licensed model. Its Q4_K_M file is about 105 MB; loading it needs additional memory for the runtime and context. This small model can run on a CPU, but its answers can be inaccurate and the wording varies. For another model, replace bartowski/SmolLM2-135M-Instruct-GGUF with your public GGUF repository and Q4_K_M with a quantization listed in its files. Ollama downloads missing weights before generating the reply.
- Confirm that Ollama retains the model under its Hugging Face reference. Example output:
$ ollama list
NAME                                                 ID              SIZE      MODIFIED
hf.co/bartowski/SmolLM2-135M-Instruct-GGUF:Q4_K_M    f7e5429e6a76    105 MB    Less than a second ago
The hf.co repository and quantization tag should match the model that answered the prompt. A missing entry or a failed generation does not confirm a usable download.
Related: How to list Ollama models