Open WebUI can use Ollama as a model provider when its backend can reach the Ollama HTTP API. The connection matters most in Docker deployments, where a URL that works from the host shell can point at the wrong network namespace from inside the Open WebUI container.
The native Ollama connection uses the server's base URL and discovers models that are already downloaded there. It is separate from an OpenAI-compatible connection, so the URL has no /v1 suffix.
An administrator account in Open WebUI and a running Ollama server with at least one model are required. A model in the picker confirms discovery, while a reply in the chat confirms that Open WebUI can also send generation requests to that server.
Steps to connect Ollama to Open WebUI:
- Check that the Ollama model is listed from the Open WebUI backend.
$ docker exec open-webui curl --fail-with-body --silent --show-error "http://ollama.example.net:11434/api/tags"
open-webui is the existing container name, and ollama.example.net represents the reachable Ollama server. A populated models array should include the model you intend to use. An empty array means the server has no downloaded models; a connection error means the backend cannot reach that address.
For a host-running Ollama service, Docker Desktop supplies host.docker.internal. On Linux bridge networks, an explicit host-gateway mapping supplies the host address for host.docker.internal, but does not change a loopback-only Ollama listener. The service must already listen on an address reachable from the container. A shared Compose network can instead use the Ollama service name.
Related: How to run Open WebUI with DockerOllama's local API has no built-in authentication. A network-accessible listener can let other people run or manage models, so it needs a private network or access controls that restrict access to trusted clients.
- Open your account menu in the lower-left corner.
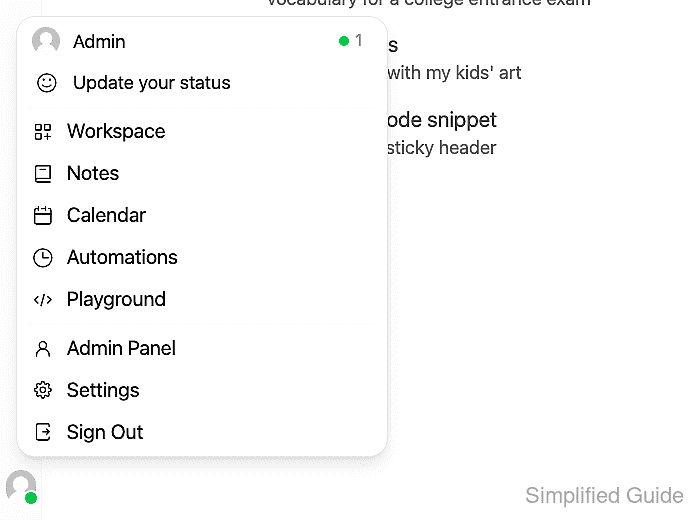
- Select Settings from the account menu.
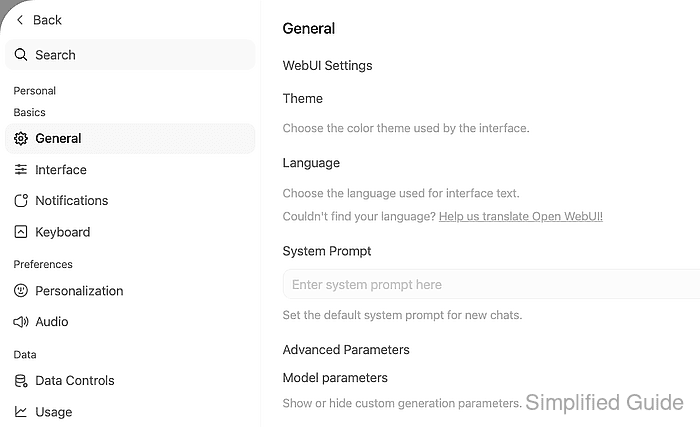
- Select Connections under Admin → AI in the settings sidebar.
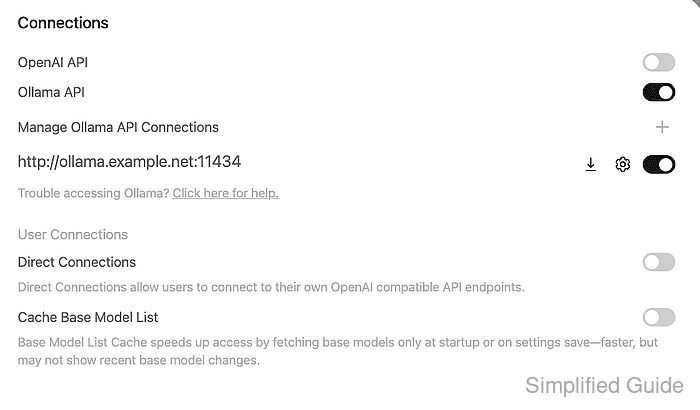
The Ollama API switch must be enabled for the native connection to be available.
- Click the Configure gear beside the existing URL under Manage Ollama API Connections.
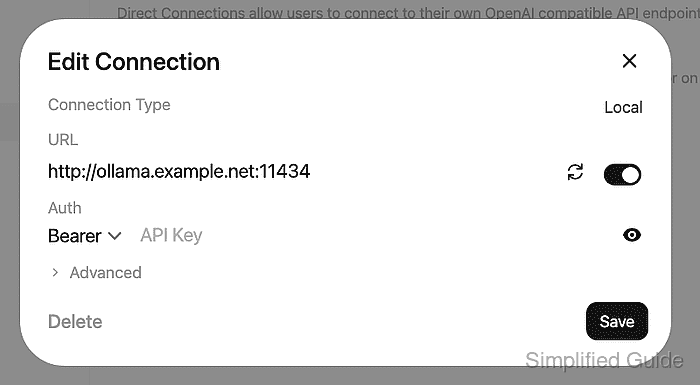
- Enter the reachable Ollama base URL in URL.
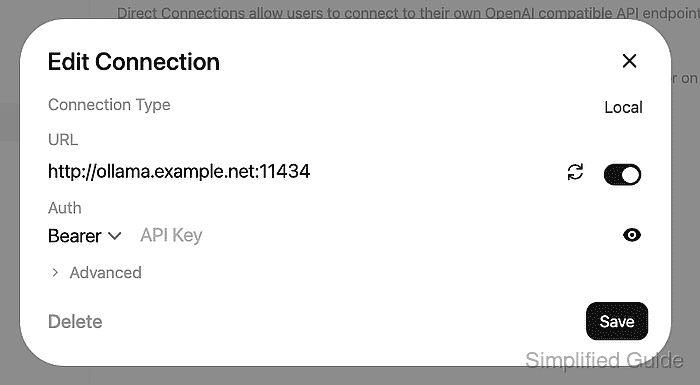
http://ollama.example.net:11434
The field takes only the base URL, without /api/tags or /v1. A host-running server can instead use the host name host.docker.internal with port 11434 when the backend probe succeeds through that address.
- Select None under Auth for the local Ollama API.
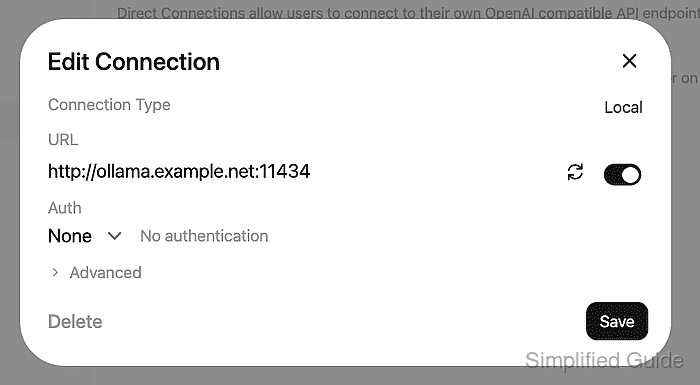
If an authentication proxy protects the endpoint, its required authentication takes precedence; Bearer is appropriate only when that proxy expects a bearer token.
- Click the circular-arrow Verify Connection control beside URL.
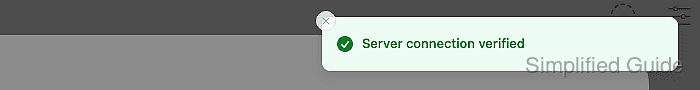
Server connection verified confirms that the backend reached Ollama. A failed verification needs a reachable URL before saving.
Related: How to fix Open WebUI localhost connection errors in Docker - Click Save in Edit Connection to connect Open WebUI to the Ollama server.
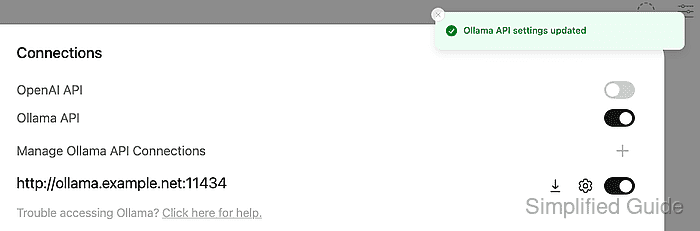
The dialog closes and Ollama API settings updated appears above the saved connection.
- Click Back to leave Settings.
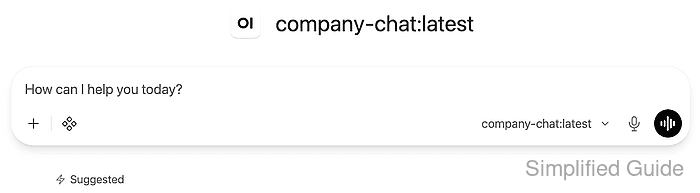
- Open New Chat with the pencil icon in the sidebar.
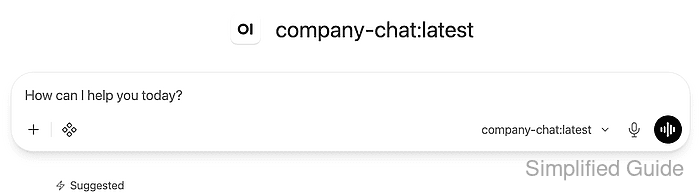
- Open the model picker in the message box.
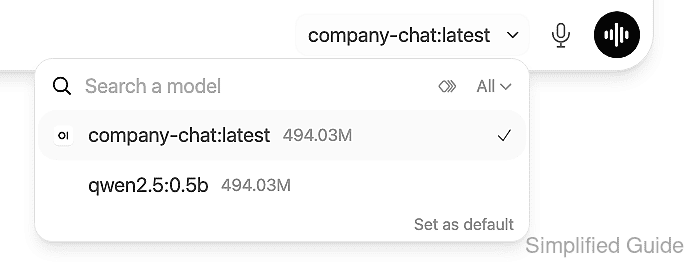
The list should include a model returned by /api/tags. If the model is missing after saving, the refresh checks can distinguish a stale list from a failed connection.
Related: How to refresh the Open WebUI model list - Select the model already available on your Ollama server.
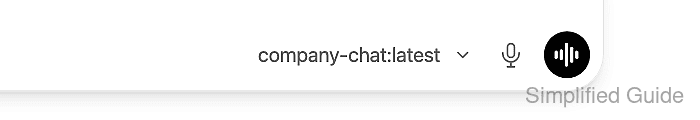
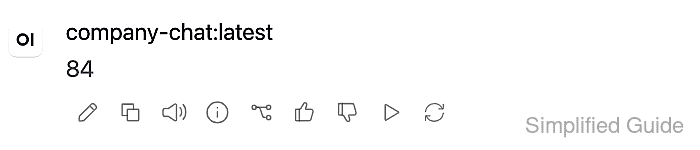
company-chat:latest is the model selected here; your server can have a different model name.
- Enter a short test question in the message box.
What is 12 multiplied by 7? Answer with the number only.
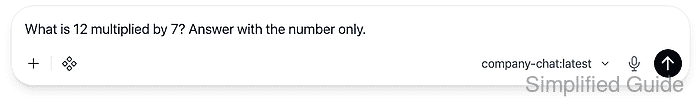
- Click Send message to submit the question.
- Confirm that the selected Ollama model returns a reply in the chat.
The model name above the reply should match your selection. A returned answer exercises the saved connection and generation route; a saved URL or a model-list entry alone does not show that chat generation works.