An empty model selector in Open WebUI can be a routing problem even when the model provider is healthy. In Docker, a connection using localhost can point back into the Open WebUI container instead of reaching the provider; a reachable provider address restores model access.
Provider connections depend on the API protocol and the network location of the Open WebUI backend. An OpenAI-compatible base URL normally ends in /v1, while its model-list endpoint adds /models. Inside a container, localhost and 127.0.0.1 identify that container rather than the Docker host or another model server.
This address repair fits an administrator-managed connection whose model-list request succeeds outside Open WebUI but fails at its saved loopback URL. The provider must already have an address reachable from the container; a model appearing again is only part of recovery, because a short chat must also receive a reply.
Steps to fix Open WebUI localhost connection errors in Docker:
- Open the Open WebUI user menu.
- Select Settings.
- Select Connections under Admin → AI.
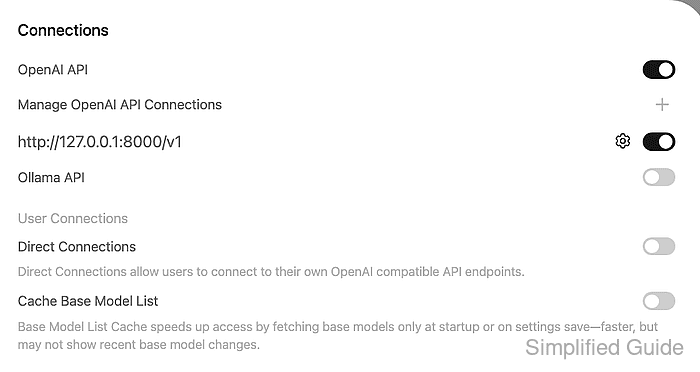
- Open the failing provider's gear control beside its URL.
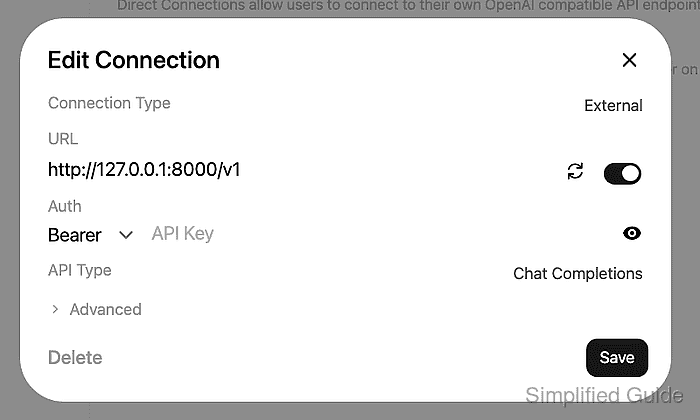
The URL field contains the base address, such as http://127.0.0.1:8000/v1, without the /models suffix.
- Click Verify Connection beside the saved loopback URL.
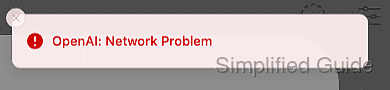
The circular-arrow control reports OpenAI: Network Problem for the unreachable address shown here; this message alone does not identify the cause.
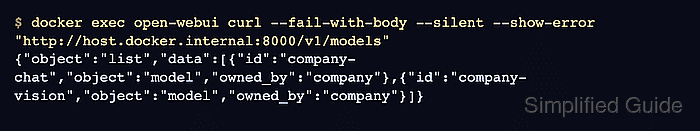
- Probe the provider's model-list endpoint from the Docker host.
$ curl --fail-with-body --silent --show-error https://llm.example.com/v1/models
A successful JSON response includes the expected model ID, such as company-chat. Here, https://llm.example.com/v1 represents the provider's existing reachable base URL. If authentication is required, a private curl configuration file can supply the authorization header without exposing the key in command arguments or shell history.
- Probe the saved loopback URL from the Open WebUI container.
$ docker exec open-webui curl --fail-with-body --silent --show-error --connect-timeout 3 http://127.0.0.1:8000/v1/models
curl: (7) Failed to connect to 127.0.0.1 port 8000 after 0 ms: Could not connect to server
This result establishes that no provider answers at this container-local address. Together with the successful provider request, it supports changing the connection address; a timeout, an authentication error, or a certificate error needs its own diagnosis.
- Probe the provider's reachable model-list URL from the Open WebUI container.
$ docker exec open-webui curl --fail-with-body --silent --show-error https://llm.example.com/v1/models
The response must contain the same expected model ID. For a provider already reachable on the Docker Desktop host, host.docker.internal addresses that host; it does not make a loopback-only listener reachable on every platform.
A public listener or broad firewall rule can expose model access and private prompts. This repair uses an existing reachable endpoint without widening listener access or disabling TLS verification.
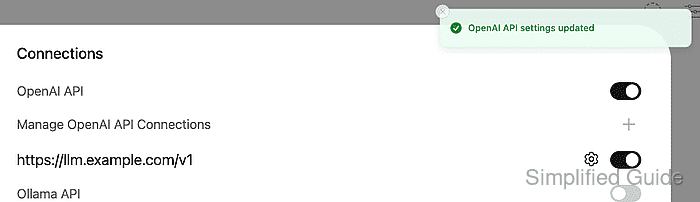
- Replace only the connection's URL with the base address that answered from the container.
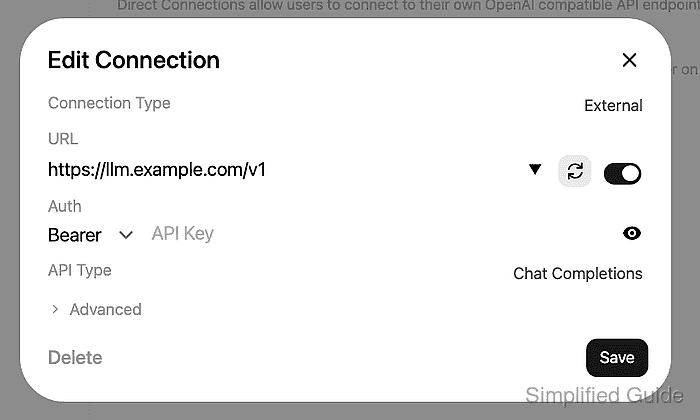
The saved value is https://llm.example.com/v1, without /models. The connection's authentication and API type remain unchanged; API keys must stay out of screenshots, tickets, and shared logs.
- Click Verify Connection beside the replacement URL.
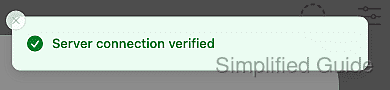
Server connection verified confirms model discovery through the replacement address.
- Save the edited connection.
- Return to chat with Back.
- Reload Open WebUI in the browser.
Reloading requests the model list again after the saved connection change. If model caching is enabled, the separate refresh control is covered in How to refresh the Open WebUI model list.
- Open the model picker in the chat composer.
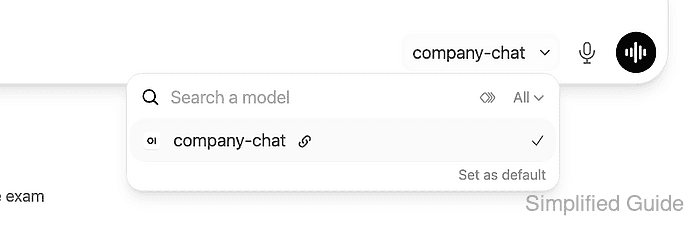
- Select the provider model that was unavailable.
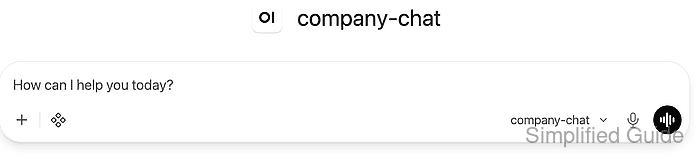
The restored model is company-chat here.
- Enter a short test prompt in the chat composer.
Write a one-sentence greeting for a new customer.
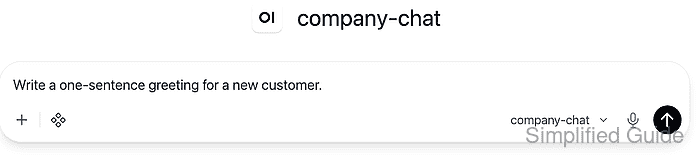
- Send the prompt with Enter.
- Confirm that the selected model's reply appears in Open WebUI.
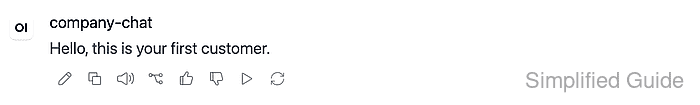
A reply proves that both model discovery and chat requests now reach the provider. If models load but chat still fails, the chat endpoint or model configuration needs further investigation.