The context window in llama.cpp controls how many prompt and generated tokens can stay available to a loaded model. Setting the context size explicitly reserves room for longer prompts, retrieved text, or conversation history within the model and hardware limits.
Both llama-server and llama-cli accept -c or --ctx-size. For a server, the total runtime context and the context available to one request can differ because of slot allocation and model limits. A single slot makes the requested window easier to compare with the active request budget.
Larger context windows increase KV cache memory use and can prevent the model from loading when memory runs out. The model's training context is a separate limit recorded in its metadata; requesting a larger number does not by itself extend the model's supported window.
Steps to set context size in llama.cpp:
- Choose a context window supported by the local chat model and available memory.
A 2048-token window leaves room for a short conversation with Qwen2.5-0.5B-Instruct Q4_K_M, which records a 32768-token training context. The local file is models/chat-model.gguf, and llama-server is already installed on PATH. The prompt budget includes conversation history and chat-template tokens as well as the new message; generated tokens also consume the window.
An existing foreground server on port 8080 must stop before its replacement can bind that port. If it is running, Ctrl+C in its terminal stops it and interrupts active requests.
- Start the model with a 2048-token context and one server slot.
$ llama-server -m models/chat-model.gguf \
  --alias local-context \
  --ctx-size 2048 --parallel 1 \
  --host 127.0.0.1 --port 8080
##### snipped #####
0.02.271.124 I srv    load_model: initializing, n_slots = 1, n_ctx_slot = 2048, kv_unified = 'false'
0.02.275.758 I srv  server_run_i: model loaded
0.02.275.787 I srv  server_on_li: listening on http://127.0.0.1:8080
The alias is local-context. With --parallel 1, the 2048-token allocation is available to that single slot, subject to the model limit. A value of 0 for --ctx-size loads the context size from the model; an explicit positive value requests that window. LLAMA_ARG_CTX_SIZE is the environment equivalent. The loopback bind keeps the listener local; it does not add authentication. The server remains running in this terminal.
- Confirm the active slot has a 2048-token context from a second terminal.
$ curl --fail --silent --show-error http://127.0.0.1:8080/props
The response's default_generation_settings.n_ctx should be 2048 and total_slots should be 1. The startup log also reports n_ctx_slot = 2048. A different slot count or lower slot context means the request budget differs from the intended single-slot window. This read-only request does not require the --props switch, which enables property changes.
- Compare the loaded context with the model's training context.
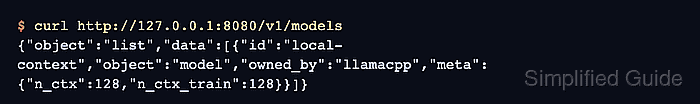
$ curl --fail --silent --show-error http://127.0.0.1:8080/v1/models
The entry under data with id set to local-context reports meta.n_ctx as 2048 and meta.n_ctx_train as 32768 for this model. The former is the runtime context reported to clients; the latter comes from model metadata. The server caps a slot at the training context, so a larger startup request can still produce a smaller slot. Other models have different metadata.
- Send a chat request within the loaded context budget.
$ curl --fail --silent --show-error http://127.0.0.1:8080/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{"model":"local-context","messages":[{"role":"user","content":"What is two plus two?"}],"max_tokens":64,"stream":false}'
{"choices":[{"finish_reason":"stop","index":0,"message":{"role":"assistant","content":"two plus two equals four."}}],"created":1793148025,"model":"local-context","system_fingerprint":"b11913-7aca0d2ea","object":"chat.completion","usage":{"completion_tokens":7,"prompt_tokens":35,"total_tokens":42,"prompt_tokens_details":{"cached_tokens":0}},"id":"chatcmpl-0e2Q6FNt2AtdkdzFvesrKSpSIGcCFFeM","timings":{"cache_n":0,"prompt_n":35,"prompt_ms":938.415,"prompt_per_token_ms":26.811857142857143,"prompt_per_second":37.29693152816185,"predicted_n":7,"predicted_ms":1778.904,"predicted_per_token_ms":296.484,"predicted_per_second":3.372863291105085}}
The assistant answer confirms that generation works with the loaded window. Here usage.prompt_tokens is 35 and usage.completion_tokens is 7, for 42 tokens within the 2048-token slot. max_tokens limits the response to 64 tokens; it does not resize the context. A nonempty assistant message and finish_reason set to stop show a completed answer. Reply wording and token counts vary with the model and prompt.