Fine-tuning can save only the weight changes instead of another full language model. A PEFT LoRA adapter must become a GGUF adapter before llama.cpp can load those changes alongside its base model.
The converted adapter stays separate from the base model rather than merging into it. It belongs with the checkpoint used during training; another model with matching tensor dimensions can load without reproducing the intended fine-tuning.
Conversion uses the original Hugging Face base configuration to map adapter tensors, while llama-server needs the base weights in GGUF format. A small public SmolLM2 adapter allows a CPU load test, and the server's adapter list identifies the converted file after loading.
Steps to convert a LoRA adapter to GGUF for llama.cpp:
- Enter the llama.cpp checkout containing the built llama-server binary.
$ cd llama.cpp
The source checkout includes the Python converter; a standalone server binary does not. The build guide supplies the compiler, Git, certificates, and build/bin/llama-server.
Related: How to build llama.cpp from source with CMake - Refresh the APT package index on Ubuntu or Debian.
$ sudo apt-get update
- Install Python virtual-environment support and curl.
$ sudo apt-get install --assume-yes python3-venv curl
Only system package installation needs sudo. Conversion and server operation run as your regular user.
- Create a Python virtual environment for adapter conversion.
$ python3 -m venv .venv-lora
- Activate the converter environment.
$ . .venv-lora/bin/activate
- Install the checkout's LoRA converter dependencies and the Hugging Face downloader.
$ pip install -r requirements/requirements-convert_lora_to_gguf.txt huggingface_hub
The requirements install PyTorch and the other conversion libraries. huggingface_hub supplies hf; the public downloads do not require sign-in.
- Download the public SmolLM2 PEFT adapter into its own directory.
$ hf download lhoestq/finetune_smollm2_python \
  --include adapter_config.json adapter_model.safetensors \
  --local-dir adapters/smollm2-python
For your own adapter, the input directory replaces adapters/smollm2-python and contains adapter_config.json plus adapter_model.safetensors. A full fine-tuned model directory is a different conversion input. Safetensors avoids the pickle-based weight format.
Related: How to convert a Hugging Face model to GGUF for llama.cpp - Read the adapter configuration to identify its training base and LoRA format.
$ cat adapters/smollm2-python/adapter_config.json
The public adapter names HuggingFaceTB/SmolLM2-135M as base_model_name_or_path and uses standard LORA with use_dora and use_rslora both false. A different adapter needs its own exact training base; the instruction-tuned SmolLM2-135M-Instruct checkpoint is not interchangeable. Unsupported architectures, extra trained embeddings, and other PEFT variants may not be handled by the upstream LoRA converter.
- Convert the adapter weights to an F16 GGUF adapter.
An existing adapters/smollm2-python.gguf can be overwritten. A new output filename preserves an earlier conversion; the PEFT input files remain unchanged.
$ python3 convert_lora_to_gguf.py adapters/smollm2-python \
  --base-model-id HuggingFaceTB/SmolLM2-135M \
  --outfile adapters/smollm2-python.gguf --outtype f16
INFO:lora-to-gguf:Loading base model from Hugging Face: HuggingFaceTB/SmolLM2-135M
##### snipped #####
INFO:gguf.gguf_writer:adapters/smollm2-python.gguf: n_tensors = 120, total_size = 1.8M
##### snipped #####
INFO:lora-to-gguf:Model successfully exported to adapters/smollm2-python.gguf
--base-model-id selects the original Hugging Face base configuration, not a GGUF file, and downloads metadata rather than the full base weights. For another adapter, this value must name its training base. --outtype f16 stores the adapter tensors in half precision.
- Download the matching base model in GGUF format.
$ hf download mradermacher/SmolLM2-135M-GGUF SmolLM2-135M.Q8_0.gguf \
  --local-dir models
The GGUF publisher identifies HuggingFaceTB/SmolLM2-135M as the source checkpoint. This is the base model, separate from the adapter. With your own adapter, the server model path must point to a GGUF made from its training base.
Related: How to convert a Hugging Face model to GGUF for llama.cpp - Start llama-server with the base model and converted adapter.
The listener exposes inference and adapter management to local clients. Binding to 127.0.0.1 keeps it off the network but does not authenticate local users.
$ ./build/bin/llama-server -m models/SmolLM2-135M.Q8_0.gguf \
  --lora adapters/smollm2-python.gguf --ctx-size 1024 \
  --host 127.0.0.1 --port 8080
The server stays in this terminal, and port 8080 must be free. The explicit port keeps the API URL independent of version-specific defaults. --lora loads the adapter at scale 1; --ctx-size 1024 limits context memory for the small CPU model. A CPU_REPACK fallback warning means the adapter uses ordinary CPU buffers; a missing tensor or incompatible shape is a load failure.
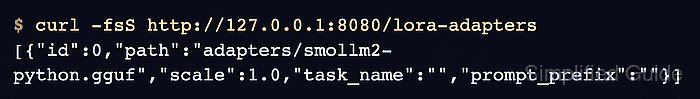
- Confirm that the running server lists the converted adapter from a second terminal. Example output:
$ curl -fsS http://127.0.0.1:8080/lora-adapters
[{"id":0,"path":"adapters/smollm2-python.gguf","scale":1.0,"task_name":"","prompt_prefix":""}]
The adapter endpoint returns loaded adapters. The path must identify the newly converted file, with id set to 0 and scale set to 1.0 for this single-adapter start. An empty list does not prove the conversion loaded. A connection error or loading response means the server is not ready; an error in its terminal needs resolving before the adapter can be used.
Related: How to set llama.cpp server LoRA adapter scales