Model providers cap how many requests an application can send in a given period and answer HTTP 429 once that cap is crossed. In a Python LangChain agent, a burst of model calls can end a run with OpenAIRateLimitError, and bounded retries with request pacing let the same run finish with its expected answer.
An agent sends a new model request after every tool result, so a single run can exceed a low limit on its own. The OpenAI SDK behind ChatOpenAI retries a 429 twice by default before the error reaches LangChain, and ModelRetryMiddleware retries around that layer, so leaving both active multiplies the requests sent while the limit applies. InMemoryRateLimiter works earlier in the path by holding each LangChain model call until its turn.
LangChain documents a MODEL_RATE_LIMIT error code, but only its JavaScript packages use it, so a Python application recognizes the failure from the exception class and the HTTP status. A small local mock server stands in for the provider and reproduces the 429 on demand with no API key or usage cost. Request pacing counts requests in one process, so token limits, limits shared between processes, and a 429 caused by exhausted billing credit need a different fix.
Steps to troubleshoot model rate limit errors in LangChain:
- Install LangChain and the OpenAI integration in the active project environment.
$ python -m pip install --upgrade langchain langchain-openai
LangChain requires Python 3.10 or newer. Tested with LangChain 1.4.9, langchain-openai 1.7.4, and openai 3.46.0 on Python 3.12 on Linux.
Related: How to create a virtual environment for LangChain
Related: How to install LangChain with pip - Create a file named mock_provider.py in your project folder using your text editor.
- Enter the imports, the request limit, and the 429 response body.
- mock_provider.py
import json
import time
from http.server import BaseHTTPRequestHandler, HTTPServer

WINDOW_SECONDS = 4
RATE_LIMIT_BODY = {
    "error": {
        "message": "Rate limit reached for requests",
        "code": "rate_limit_exceeded",
    }
}
last_allowed = 0.0
The mock accepts one request every four seconds, a limit low enough for one agent run to exceed.
- Add a function below the constants that answers a user message with a tool call and a tool result with the final reply.
def next_message(messages):
    last = messages[-1]
    if last["role"] == "tool":
        text = f"Order 1042 is {last['content']}."
        return {"role": "assistant", "content": text}
    arguments = json.dumps({"order_id": "1042"})
    function = {"name": "order_status", "arguments": arguments}
    call = {
        "id": "call_1",
        "type": "function",
        "function": function,
    }
    return {"role": "assistant", "tool_calls": [call]}
The final reply repeats the tool result it receives, so the expected answer can only appear after the agent's second model call succeeds.
- Add the request handler at the end of the file to answer 429 inside the window and a model reply outside it.
class MockProvider(BaseHTTPRequestHandler):
    def do_POST(self):
        global last_allowed
        size = int(self.headers["Content-Length"])
        request = json.loads(self.rfile.read(size))
        if time.time() - last_allowed < WINDOW_SECONDS:
            self.respond(429, RATE_LIMIT_BODY)
            return
        last_allowed = time.time()
        message = next_message(request["messages"])
        choice = {"message": message, "finish_reason": "stop"}
        self.respond(200, {"choices": [choice]})
- Add the response method, the request log, and the server start at the end of the file.
    def respond(self, status, payload):
        body = json.dumps(payload).encode()
        self.send_response(status)
        self.send_header("Content-Type", "application/json")
        self.send_header("Content-Length", str(len(body)))
        self.end_headers()
        self.wfile.write(body)

    def log_request(self, code="-", size="-"):
        stamp = time.strftime("%H:%M:%S")
        print(stamp, "HTTP", code, flush=True)


print("Mock provider listening on 127.0.0.1:8765", flush=True)
HTTPServer(("127.0.0.1", 8765), MockProvider).serve_forever()
The first two methods keep their indentation because they belong to MockProvider. The log prints the time and status of each request.
- Save mock_provider.py.
- Start the mock provider in a second terminal from your project folder.
$ python3 mock_provider.py
Mock provider listening on 127.0.0.1:8765
The mock uses only the Python standard library, so this terminal needs no active environment. The server keeps running here and logs every request.
- Create a file named agent_run.py in the same folder using your text editor.
- Enter the imports and timestamped logging.
- agent_run.py
import logging

from langchain.agents import create_agent
from langchain.tools import tool
from langchain_openai import ChatOpenAI

logging.basicConfig(
    format="%(asctime)s %(message)s",
    datefmt="%H:%M:%S",
)
logging.getLogger("openai").setLevel(logging.INFO)
The openai logger reports SDK retries at INFO level, so setting it here shows retries that are otherwise silent.
- Add the tool and the chat model below the logging setup.
@tool
def order_status(order_id: str) -> str:
    """Look up the delivery status of an order."""
    return "out for delivery"


model = ChatOpenAI(
    model="mock-model",
    base_url="http://127.0.0.1:8765/v1",
    api_key="not-used",
)
base_url sends the requests to the mock, which never reads api_key. ChatOpenAI sets no retry count of its own here, so the SDK default of two retries applies.
- Add the agent and one run at the end of the file.
agent = create_agent(model=model, tools=[order_status])
question = {"role": "user", "content": "Where is order 1042?"}
result = agent.invoke({"messages": [question]})
print(result["messages"][-1].text)
This run needs two model requests. The first returns the tool call, and the second carries the tool result straight back to the model.
- Save agent_run.py.
- Run the agent from your project folder in the terminal with the active environment.
$ python agent_run.py
22:56:00 Retrying request in 0.485450 seconds (retry 1 of 2)
22:56:00 Retrying request in 0.862899 seconds (retry 2 of 2)
Traceback (most recent call last):
##### snipped #####
langchain_openai.chat_models.base.OpenAIRateLimitError:
Error code: 429 - Rate limit reached for requests
##### snipped #####
The run stops on OpenAIRateLimitError, which inherits from both openai.RateLimitError and LangChain's ModelRateLimitError. The two Retrying request lines are the SDK's own retries, made before the exception reaches LangChain.
- Read the message after Error code: 429 to confirm a request-rate limit.
The message Rate limit reached for requests reports a limit that clears with time. A billing 429 such as Credit balance exhausted raises the same exception class, but retrying cannot restore access, so it needs a billing or limit change instead.
- Check the request log in the mock provider terminal.
22:56:00 HTTP 200
22:56:00 HTTP 429
22:56:00 HTTP 429
22:56:01 HTTP 429
The 200 answers the first model request. The three 429 lines are the second model call sent once and retried twice by the SDK, all inside the four-second window.
- Open agent_run.py in your text editor.
- Add the following imports directly below the ChatOpenAI import.
from langchain.agents.middleware import ModelRetryMiddleware
from langchain_core.exceptions import ModelRateLimitError
- Add the following line inside the ChatOpenAI call, directly below api_key.
max_retries=0,
This turns off the SDK retries so that the middleware holds the only retry budget. With both active, the four middleware attempts configured next send 12 requests during a sustained limit instead of 4.
- Replace the agent line with a retry function, the middleware, and a new agent definition.
The old line is:
agent = create_agent(model=model, tools=[order_status])
The replacement block is:
def retry_rate_limit(exc):
    name = type(exc).__name__
    logging.warning("Model call failed: %s", name)
    return isinstance(exc, ModelRateLimitError)


retry = ModelRetryMiddleware(
    max_retries=3,
    initial_delay=2.0,
    retry_on=retry_rate_limit,
    on_failure="error",
)
agent = create_agent(
    model=model,
    tools=[order_status],
    middleware=[retry],
)
retry_rate_limit logs each failure and retries only rate limits, so an authentication error stops the run at once. The middleware waits about 2, 4, and 8 seconds with random variation of up to 25%. It does not read a Retry-After header, so a retry can arrive before the wait a provider asks for. on_failure="error" raises the exception after the last retry. The default, continue, returns the failure text as the agent's reply and lets the program exit normally.
- Save agent_run.py.
- Run the agent again from your project folder.
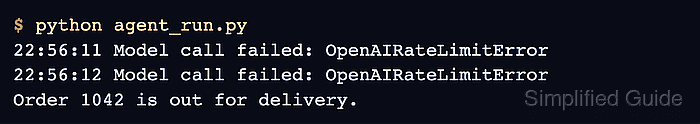
$ python agent_run.py
22:56:11 Model call failed: OpenAIRateLimitError
22:56:12 Model call failed: OpenAIRateLimitError
Order 1042 is out for delivery.
Each log line is a failed attempt, and the reply shows that the same run reached the tool result and finished.
- Check the newest lines in the mock provider terminal.
22:56:11 HTTP 200
22:56:11 HTTP 429
22:56:12 HTTP 429
22:56:17 HTTP 200
The 429 lines followed by a 200 show the backoff outlasting the window. The gaps between requests vary slightly from run to run because of the random variation.
- Open agent_run.py in your text editor again.
- Add the following import directly below the other imports.
from langchain.rate_limiters import InMemoryRateLimiter
- Add the rate limiter directly above the model definition.
limiter = InMemoryRateLimiter(
    requests_per_second=0.2,
    max_bucket_size=1,
)
0.2 requests per second is one request every five seconds, just under the mock's limit. For a hosted provider, use a value below the request limit published for your account. A larger max_bucket_size saves unused capacity and can release it as a burst. Each process keeps its own bucket, so two processes sharing a limit can still exceed it. LangChain rate limiting covers the same settings.
- Add the following line inside the ChatOpenAI call, directly below max_retries.
rate_limiter=limiter,
Each middleware retry waits for the limiter as well. SDK retries bypass it, which is a second reason to keep max_retries=0.
- Save agent_run.py.
- Run the paced agent from your project folder.
$ python agent_run.py
Order 1042 is out for delivery.
No failure lines appear before the reply. The first request also waits about five seconds because the bucket starts empty.
- Check the newest lines in the mock provider terminal for two successful requests at least five seconds apart.
22:56:30 HTTP 200
22:56:36 HTTP 200
Two 200 lines with no 429 between them show the run stayed under the limit. The retry middleware stays in place for a 429 that pacing does not prevent. An existing agent takes the same max_retries, rate_limiter, and middleware settings on its own ChatOpenAI and create_agent calls.
- Press Ctrl+C in the mock provider terminal to stop the server.