Haystack retrieval pipelines often need a reranking pass when the first retriever returns several plausible documents. A Sentence Transformers ranker scores each candidate against the query with a cross-encoder model, so a search or RAG pipeline can put the most relevant document first before it sends context downstream.
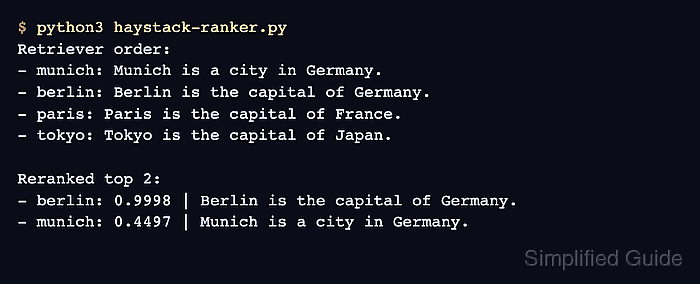
The SentenceTransformersSimilarityRanker component lives in the sentence-transformers-haystack integration package. It receives candidate documents from a retriever and the same query string through Pipeline.run(), then returns Document objects sorted by ranker score.
An InMemoryBM25Retriever dataset makes the reranking boundary visible without requiring a vector database. The retriever top_k value controls the candidate pool sent to the cross-encoder, and the ranker top_k value controls how many scored documents leave the final component.
Steps to use a Sentence Transformers ranker in Haystack:
- Install the Sentence Transformers Haystack integration in the active Python environment.
$ python3 -m pip install --upgrade sentence-transformers-haystack
##### snipped #####
Successfully installed sentence-transformers-5.6.0 sentence-transformers-haystack-0.1.0
The integration package installs haystack-ai, sentence-transformers, transformers, and torch dependencies when they are missing. Use a virtual environment when the project should not share Python packages with the system interpreter.
Related: How to create a virtualenv for Haystack
Related: How to install Haystack with pip - Check the ranker import path and default model.
$ python3 - <<'PY'
from haystack_integrations.components.rankers.sentence_transformers import (
    SentenceTransformersSimilarityRanker,
)

ranker = SentenceTransformersSimilarityRanker(top_k=2)
print(type(ranker).__name__)
print(ranker.model)
print(ranker.top_k)
PY
SentenceTransformersSimilarityRanker
cross-encoder/ms-marco-MiniLM-L-6-v2
2
Pass a different model value only when the project has a tested cross-encoder model for its language, domain, or latency target.
- Create a query pipeline script that places the ranker after a BM25 retriever.
$ cat > haystack-ranker.py <<'PY'
from haystack import Document, Pipeline
from haystack.components.retrievers.in_memory import InMemoryBM25Retriever
from haystack.document_stores.in_memory import InMemoryDocumentStore
from haystack_integrations.components.rankers.sentence_transformers import (
    SentenceTransformersSimilarityRanker,
)

query = "What is the capital city of Germany?"

documents = [
    Document(content="Munich is a city in Germany.", meta={"name": "munich"}),
    Document(content="Berlin is the capital of Germany.", meta={"name": "berlin"}),
    Document(content="Paris is the capital of France.", meta={"name": "paris"}),
    Document(content="Tokyo is the capital of Japan.", meta={"name": "tokyo"}),
]

document_store = InMemoryDocumentStore()
document_store.write_documents(documents)

retriever = InMemoryBM25Retriever(document_store=document_store, top_k=4)
ranker = SentenceTransformersSimilarityRanker(top_k=2)

pipeline = Pipeline()
pipeline.add_component("retriever", retriever)
pipeline.add_component("ranker", ranker)
pipeline.connect("retriever.documents", "ranker.documents")

retriever_result = retriever.run(query=query)
print("Retriever order:")
for document in retriever_result["documents"]:
    print(f"- {document.meta['name']}: {document.content}")

result = pipeline.run(
    {
        "retriever": {"query": query},
        "ranker": {"query": query},
    }
)

print()
print("Reranked top 2:")
for document in result["ranker"]["documents"]:
    print(f"- {document.meta['name']}: {document.score:.4f} | {document.content}")

top_document = result["ranker"]["documents"][0]
assert top_document.meta["name"] == "berlin"

print()
print(f"Final top document: {top_document.meta['name']}")
PY
The first run downloads the cross-encoder model unless it is already cached. Private Hugging Face models need an HF_TOKEN or HF_API_TOKEN environment variable.
- Run the pipeline script.
$ python3 haystack-ranker.py
Retriever order:
- munich: Munich is a city in Germany.
- berlin: Berlin is the capital of Germany.
- paris: Paris is the capital of France.
- tokyo: Tokyo is the capital of Japan.

Reranked top 2:
- berlin: 0.9998 | Berlin is the capital of Germany.
- munich: 0.4497 | Munich is a city in Germany.

Final top document: berlin
Small score differences can appear across model and runtime versions. The important signal is that the ranker output returns berlin first and limits the final list to two documents.