Website migrations preserve old links only when every retired address has an explicit outcome. A redirect map is the decision record that pairs each legacy URL with its final replacement or marks the content as deliberately gone before any server rule is written.
Store the map as UTF-8 CSV with one row per legacy URL and the columns source_url, target_url, decision, and owner. Use redirect only when a destination replaces or consolidates the old content, and use gone with an empty target when no relevant replacement exists.
A release-ready map has no duplicate sources, self-redirects, chains, loops, malformed URLs, or unavailable destinations. Check targets against the prepared replacement site so every redirect points directly to a page that already returns 200 OK.
Steps to create a website redirect map:
- Freeze the complete legacy URL inventory from sitemaps, the content management system, server logs, analytics, inbound-link records, and active protocol or hostname variants.
- old-urls.txt
https://old.example.com/guides/seo
https://old.example.com/services/seo
https://old.example.com/about-us
https://old.example.com/spring-offer
The inventory also covers indexed images, downloads, and other files that will move.
- Create redirect-map.csv with one approved decision and accountable owner for every frozen source URL.
- redirect-map.csv
source_url,target_url,decision,owner
https://old.example.com/guides/seo,https://www.example.net/resources/seo-audit,redirect,content
https://old.example.com/services/seo,https://www.example.net/resources/seo-audit,redirect,content
https://old.example.com/about-us,https://www.example.net/about,redirect,communications
https://old.example.com/spring-offer,,gone,marketing
Several legacy pages may share one destination only when that page genuinely consolidates their content. An unrelated home-page target is not a replacement and can be treated as a soft error by search engines.
- Create validate_redirect_map.py with the CSV schema and absolute-URL check.
- validate_redirect_map.py
#!/usr/bin/env python3
import csv
import sys
from collections import Counter
from urllib.error import HTTPError, URLError
from urllib.parse import urlsplit
from urllib.request import Request, urlopen

FIELDS = ["source_url", "target_url", "decision", "owner"]


def valid_url(value):
    parts = urlsplit(value)
    return parts.scheme in {"http", "https"} and bool(parts.netloc)
- Append the CSV loader to validate_redirect_map.py.
def load_map(path):
    with open(path, newline="", encoding="utf-8") as handle:
        reader = csv.DictReader(handle)
        if reader.fieldnames != FIELDS:
            raise ValueError(f"expected header: {','.join(FIELDS)}")
        rows = list(reader)
    if not rows:
        raise ValueError("redirect map is empty")
    return rows
- Append the structural map checks to validate_redirect_map.py.
def structural_problems(rows):
    problems = []
    source_counts = Counter(row["source_url"] for row in rows)
    redirect_sources = {
        row["source_url"]
        for row in rows
        if row["decision"] == "redirect"
    }

    for source, count in source_counts.items():
        if count > 1:
            problems.append(f"duplicate source: {source}")

    for line_number, row in enumerate(rows, start=2):
        source = row["source_url"]
        target = row["target_url"]
        decision = row["decision"]
        if not valid_url(source):
            problems.append(f"line {line_number}: invalid source URL")
        if decision not in {"redirect", "gone"}:
            problems.append(f"line {line_number}: decision must be redirect or gone")
        if decision == "redirect" and not valid_url(target):
            problems.append(f"line {line_number}: redirect requires an absolute target URL")
        if decision == "gone" and target:
            problems.append(f"line {line_number}: gone decision must not have a target")
        if source == target:
            problems.append(f"line {line_number}: self-redirect")
        if decision == "redirect" and target in redirect_sources:
            problems.append(f"line {line_number}: chain target is also a redirect source")
    return problems
A destination that is also a redirect source creates an avoidable intermediate hop and can participate in a loop, so the map requires the final URL directly.
- Append the live destination checks to validate_redirect_map.py.
def target_problems(rows):
    problems = []
    targets = sorted({
        row["target_url"]
        for row in rows
        if row["decision"] == "redirect"
    })
    for target in targets:
        request = Request(target, headers={"User-Agent": "redirect-map-check/1.0"})
        try:
            with urlopen(request, timeout=10) as response:
                if response.status != 200:
                    problems.append(f"target returned {response.status}: {target}")
                if response.geturl() != target:
                    problems.append(f"target redirects to {response.geturl()}: {target}")
        except HTTPError as error:
            problems.append(f"target returned {error.code}: {target}")
        except URLError as error:
            problems.append(f"target request failed for {target}: {error.reason}")
    return problems, len(targets)
- Append the program entry point to validate_redirect_map.py.
def main():
    try:
        rows = load_map(sys.argv[1])
    except (IndexError, OSError, ValueError) as error:
        print(f"FAIL: {error}")
        return 1

    problems = structural_problems(rows)
    destination_problems, target_count = target_problems(rows)
    problems.extend(destination_problems)
    if problems:
        for problem in problems:
            print(f"FAIL: {problem}")
        return 1

    redirect_count = sum(row["decision"] == "redirect" for row in rows)
    gone_count = sum(row["decision"] == "gone" for row in rows)
    print(f"PASS: {len(rows)} map rows checked")
    print(f"PASS: {redirect_count} redirect decisions and {gone_count} gone decision")
    print(f"PASS: {target_count} unique targets returned 200 without redirecting")
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
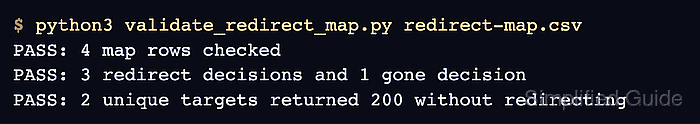
- Run the validator against redirect-map.csv from a network that can reach the prepared replacement site.
$ python3 validate_redirect_map.py redirect-map.csv
PASS: 4 map rows checked
PASS: 3 redirect decisions and 1 gone decision
PASS: 2 unique targets returned 200 without redirecting
The validator sends one authenticated-free GET request to each unique target. Large maps can create noticeable load, and private, signed, session-bound, or unauthorized URLs do not belong in the check.