Applications using the Responses API send instructions separately from user input and receive typed output items. The llama.cpp endpoint accepts a basic text request in that format and returns generated text from a local GGUF model.
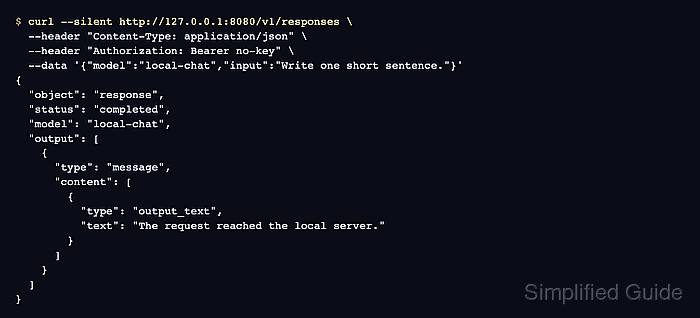
In llama.cpp, the Responses route converts the request into a Chat Completions request internally. The shared chat handling means the model needs a supported chat template, normally taken from its GGUF metadata. Compatibility covers the implemented request fields rather than every feature of the OpenAI Responses API.
A running chat-capable llama-server on 127.0.0.1:8080, curl, and Python 3 are the starting requirements. A completed response contains assistant text inside the output array and reports input and output token usage. The response envelope is JSON even when the generated text is ordinary prose.
Steps to call the llama.cpp Responses API:
- Discover the model ID for the Responses request.
$ curl --fail --silent --show-error http://127.0.0.1:8080/v1/models | \
  python3 -c 'import json, sys
for model in json.load(sys.stdin)["data"]:
    print(model["id"])'
local-chat
The data array reports local-chat as the id here. The request's model field must match the ID returned by your server; an alias provides a stable name. A loading model can return HTTP 503, which makes curl –fail exit with an error.
Related: How to start the llama.cpp server
Related: How to check llama.cpp server health - Submit the instructions and input to /v1/responses.
$ curl --fail --silent --show-error http://127.0.0.1:8080/v1/responses \
  --header 'Content-Type: application/json' \
  --data '{
    "model": "local-chat",
    "instructions": "Answer in one short sentence.",
    "input": "What is two plus two?",
    "max_output_tokens": 64
  }' \
  --output response.json \
  --write-out 'HTTP %{http_code}\n'
HTTP 200
instructions sets the reply style, input supplies the question, and max_output_tokens caps generated tokens. The response body is saved in response.json. No authorization header is needed for a local server without API-key checking.
The unauthenticated server must remain bound to loopback. A public listener can expose prompts and model access to other computers; loopback alone does not add authentication.
- Confirm that the response contains completed assistant output.
$ python3 - <<'PYTHON'
import json
with open("response.json") as response_file:
    response = json.load(response_file)
assert response["object"] == "response"
assert response["status"] == "completed"
assert response["model"] == "local-chat"
texts = [part["text"] for item in response["output"]
         if item["type"] == "message" and item["role"] == "assistant"
         for part in item["content"] if part["type"] == "output_text"]
assert texts and all(text.strip() for text in texts)
usage = response["usage"]
assert usage["input_tokens"] > 0 and usage["output_tokens"] > 0
print("object:", response["object"])
print("status:", response["status"])
print("model:", response["model"])
print("output_text:", "\n".join(texts))
print("tokens:", usage["input_tokens"], "input,", usage["output_tokens"], "output")
PYTHON
object: response status: completed model: local-chat output_text: Two plus two equals four. tokens: 25 input, 7 output
The assertions fail on an unexpected object, incomplete response, wrong model, empty assistant text, or missing token usage. If your server reports a different model ID, the request and the model assertion need that same ID. Generated wording and token counts vary between models and requests.