Model weights can consume more disk space and memory than a local machine can spare. llama.cpp can quantize a higher-precision GGUF model into a smaller copy for local inference.
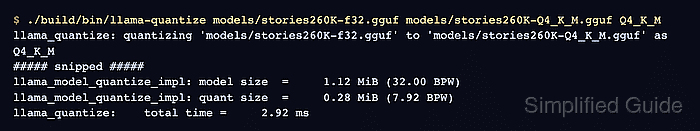
The llama-quantize tool reads one GGUF input file and writes a separate output file, so the original model remains available for comparison or a different quantization pass. Source builds expose the binary under build/bin, while package-managed installs may place llama-quantize directly on the shell path.
An F16, BF16, or F32 source avoids the additional quality loss of requantizing an already quantized model. Quantization still trades precision for size, so a successful load does not establish that the smaller model retains the original response quality.
Steps to quantize a GGUF model with llama.cpp:
- Check the higher-precision input model before creating the quantized copy.
$ ls -lh models/smollm2-135m-f16.gguf
-r--r--r-- 1 root root 259M Oct 28 00:28 models/smollm2-135m-f16.gguf
models/smollm2-135m-f16.gguf is the F16 output from the conversion guide. A different source needs its own path in the quantization and comparison commands.
Related: How to convert a Hugging Face model to GGUF for llama.cpp - Check the free disk space available for the output model.
$ df -h models
Filesystem      Size  Used Avail Use% Mounted on
/dev/vda1       1.8T  191G  1.6T  11% /work
The destination needs room for the new file while the source remains on disk. Larger models also need enough memory for quantization and the later load test; the output size depends on the model and tensor types.
- Quantize the F16 input into a separate Q4_K_M output file.
An existing file at models/smollm2-135m-Q4_K_M.gguf can be overwritten. A new output name preserves an earlier result; the output must differ from the input path.
$ llama-quantize models/smollm2-135m-f16.gguf models/smollm2-135m-Q4_K_M.gguf Q4_K_M
load_backend: loaded CPU backend from /app/libggml-cpu-armv8.2_2.so
version: 0.7.0-dev (build 11913, commit 7aca0d2ea)
built with GNU 14.2.0 for Linux aarch64
llama_quantize: quantizing 'models/smollm2-135m-f16.gguf' to 'models/smollm2-135m-Q4_K_M.gguf' as Q4_K_M
##### snipped #####
llama_model_quantize_impl: model size  =   256.63 MiB (16.00 BPW)
llama_model_quantize_impl: quant size  =    98.87 MiB (6.17 BPW)
llama_model_quantize_impl: WARNING: 180 of 272 tensor(s) required fallback quantization

llama_quantize: quantize time =  1717.25 ms
llama_quantize:    total time =  1717.25 ms
Q4_K_M selects a mixture of tensor types, rather than making every weight four bits. This model has tensor dimensions that require fallback types, which explains the warning and the 6.17 BPW tensor average. The file remains usable when the subsequent load succeeds. The optional --allow-requantize flag permits already quantized input, but can severely reduce quality compared with a higher-precision source.
If the tools are in a source build, ./build/bin/llama-quantize and ./build/bin/llama-cli replace the bare command names.
- Compare the input and output file sizes in bytes.
$ wc -c models/smollm2-135m-f16.gguf models/smollm2-135m-Q4_K_M.gguf
270885408 models/smollm2-135m-f16.gguf
105453600 models/smollm2-135m-Q4_K_M.gguf
376339008 total
The quantized file is about 61% smaller here. These whole-file byte counts include metadata; the quantizer's MiB and BPW summary describes tensor data.
- Load the quantized file with a short single-turn prompt.
$ llama-cli -m models/smollm2-135m-Q4_K_M.gguf -p "Once upon a time" -n 32 --single-turn
##### snipped #####
build      : b11913-7aca0d2ea
model      : models/smollm2-135m-Q4_K_M.gguf
ftype      : Q4_K - Medium
modalities : text
##### snipped #####
> Once upon a time
once upon a time
Once upon a time
The first

The first
##### snipped #####

[ Prompt: 24.6 t/s | Generation: 1.7 t/s ]
##### snipped #####
Exiting...
The model path identifies the new file, and the text after the prompt shows that it generated tokens. --single-turn returns to the shell after one response. A small base model can repeat itself, as shown here; wording and timings vary. A load error or no generated text means the quantized model has not passed this test.