HDFS stores file blocks on DataNodes and uses heartbeats to track which workers are available. A missing Hadoop DataNode can still hold intact replicas, so restoring it starts with diagnosing the worker rather than replacing its data.
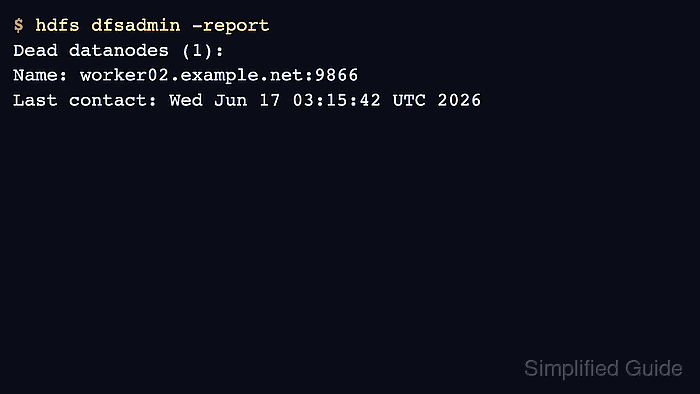
The NameNode lists a previously registered worker as dead after its heartbeat timeout expires. A worker that never registered may be absent from the report entirely, and a decommissioning worker has a different administrative state from a failed daemon.
Apache Hadoop 3 archive installations run DataNode daemon commands as the existing HDFS service account. Restoring that account's directory ownership is appropriate when the log identifies unreadable storage and inspection shows that the directory has accidentally become root-owned.
Formatting HDFS, deleting DataNode storage, or editing its VERSION files can destroy replicas or disconnect them from the cluster. A heartbeat failure does not justify those changes.
Steps to troubleshoot a missing Hadoop DataNode:
- Identify the missing worker in the NameNode's dead-node report.
$ hdfs dfsadmin -report -dead
##### snipped #####
Dead datanodes (1):
##### snipped #####
Hostname: worker02.example.net
Decommission Status : Normal
##### snipped #####
This report needs HDFS administrator access and the cluster's active configuration. Normal under Decommission Status does not mean the dead worker is healthy. If the worker has never appeared, hdfs getconf -confKey fs.defaultFS on that worker should identify the intended cluster; an HA installation normally uses its logical nameservice URI.
- Check for a DataNode JVM as the HDFS service account on the missing worker.
$ jps -l
224 jdk.jcmd/sun.tools.jps.Jps
No org.apache.hadoop.hdfs.server.datanode.DataNode process appears here. A different account can hide JVM details, and a running JVM alone does not prove registration with the NameNode. If the DataNode is already running, the storage-startup repair does not match that state.
- Read the recent DataNode log on the affected worker.
$ tail -n 40 /var/log/hadoop/hdfs/hadoop-hdfs-datanode-worker02.example.net.log
##### snipped #####
org.apache.hadoop.util.DiskChecker$DiskErrorException: Directory is not readable: /data/hadoop/hdfs/data
##### snipped #####
org.apache.hadoop.util.DiskChecker$DiskErrorException: Too many failed volumes - current valid volumes: 0, volumes configured: 1, volumes failed: 1, volume failures tolerated: 0
##### snipped #####
The log path depends on HADOOP_LOG_DIR, the daemon account, and the worker hostname; archive installations otherwise normally use $HADOOP_HOME/logs. This error identifies local storage access, rather than a heartbeat setting, as the failed startup check. Connection errors or cluster-ID mismatches require a different repair.
- Identify the worker's configured DataNode storage directory.
$ hdfs getconf -confKey dfs.datanode.data.dir
file:///data/hadoop/hdfs/data
The value comes from the worker's active Hadoop configuration. With multiple comma-separated directories, the path named in the log identifies the affected volume.
- Inspect ownership of the storage directory named in the error.
$ ls -ld /data/hadoop/hdfs/data
drwx------ 1 root root 4096 Nov  8 06:18 /data/hadoop/hdfs/data
Here, mode 700 allows only root to access a directory that the hdfs account needs. If the path normally sits on a separate disk, the expected filesystem must be mounted before any ownership change; changing an underlying empty directory can hide a missing mount.
- Restore the affected directory's HDFS ownership from a root administrator shell.
This changes access to the specified directory. The account and group must be the existing DataNode owner, which may differ from hdfs:hadoop on your installation. This repair applies only to the confirmed ownership error above; it does not require recursive changes, broader permissions, or changes to stored blocks.
# chown hdfs:hadoop /data/hadoop/hdfs/data
- Start the DataNode as its HDFS service account on the repaired worker.
$ hdfs --daemon start datanode
The daemon can start without terminal output. For a service-managed distribution, the installed service manager owns the start operation instead. A start that immediately exits still needs its log error resolved.
- Confirm that the recovered worker appears in the NameNode's live report.
$ hdfs dfsadmin -report -live
##### snipped #####
Live datanodes (2):
##### snipped #####
Hostname: worker01.example.net
Decommission Status : Normal
##### snipped #####
Hostname: worker02.example.net
Decommission Status : Normal
##### snipped #####
Last contact: Sun Nov 08 06:18:44 GMT 2026
##### snipped #####
The recovered hostname must be in the live list with the intended administrative state and a recent Last contact. The total depends on your cluster size. If it disappears again, the newest worker log is the next diagnostic signal.