A base Transformer checkpoint supplies token representations, but it does not necessarily include a sentence-embedding pipeline. Through Sentence Transformers 5.3, the “No sentence-transformers model found” warning reports that missing pipeline; explicitly defining and saving its modules removes the fallback warning on later loads.
For BERT, the fallback adds mean pooling to turn token vectors into one vector per sentence, and the warning alone does not mean that loading failed. Explicitly constructing the same Transformer and Pooling modules makes that choice part of the saved model, so reloading no longer needs to infer the architecture.
This approach fits an intentional choice to use a base BERT checkpoint. Adding pooling does not train BERT for semantic similarity or retrieval, and producing embeddings does not establish their quality. A trained sentence-embedding model remains a better starting point when the application needs ready-made semantic embeddings.
Steps to fix the "No sentence-transformers model found" warning in Sentence Transformers:
- Reproduce the warning on Sentence Transformers 5.3.0 or earlier by loading the base BERT checkpoint.
$ python -c "from sentence_transformers import SentenceTransformer; SentenceTransformer('google-bert/bert-base-uncased')"
No sentence-transformers model found with name google-bert/bert-base-uncased. Creating a new one with mean pooling.
##### snipped #####
The code uses the Sentence Transformers 5.3 API and was tested with version 5.3.0 on Python 3.12, the last release that logs this warning. Versions from 5.4.0 add the same mean pooling without logging this warning, so a newer install has nothing to fix unless the project wants the pooling saved explicitly. The first load downloads the public BERT model and tokenizer. If you expected a trained Sentence Transformers model, a wrong model ID or an incomplete local directory needs correction instead of replacing its architecture. A mistyped ID logs this warning and then stops with an error.
Related: How to install Sentence Transformers with pip - Create build_model.py in your text editor with the Transformer module definition.
- build_model.py
from sentence_transformers import SentenceTransformer, models

transformer = models.Transformer(
    "google-bert/bert-base-uncased"
)
The Transformer supplies BERT's token embeddings. The checkpoint is BERT base uncased, not a model fine-tuned for sentence similarity.
- Add the mean-pooling module at the end of build_model.py.
pooling = models.Pooling(
    transformer.get_word_embedding_dimension(),
    pooling_mode="mean",
)
The pooling dimension comes from the Transformer rather than a separately entered constant. Mean pooling averages the token embeddings while excluding padding.
- Append the model assembly block to build_model.py.
model = SentenceTransformer(modules=[transformer, pooling])
model.save_pretrained("bert-mean-pooling")
The destination bert-mean-pooling must be a new directory in the current working directory. Saving into an existing model directory can replace its files.
- Save build_model.py.
- Run build_model.py to save the explicit sentence-embedding model.
$ python build_model.py
Warning: You are sending unauthenticated requests to the HF Hub. Please set a HF_TOKEN to enable higher rate limits and faster downloads.
##### snipped #####
[transformers] BertModel LOAD REPORT from: google-bert/bert-base-uncased
##### snipped #####
cls.seq_relationship.bias                  | UNEXPECTED |  |
##### snipped #####
The original fallback warning is gone because both modules are now declared explicitly. The Hub message and the UNEXPECTED report are harmless: the cls.* keys are BERT's pretraining heads, which a plain BertModel does not use. Neither appears with Transformers 4.57.6. The saved directory contains the Transformer weights and tokenizer, modules.json describing the pipeline, and the Pooling configuration. On version 5.4.0 or later, the same run also prints deprecation messages for the 5.3 API, and the replacement lines below avoid them.
Related: How to migrate Sentence Transformers code to v6
Related: How to save and reload a Sentence Transformers model
Related: Custom model documentation with the newer importsfrom sentence_transformers import SentenceTransformer from sentence_transformers.sentence_transformer.modules import ( Pooling, Transformer, ) transformer = Transformer("google-bert/bert-base-uncased") pooling = Pooling( transformer.get_embedding_dimension(), pooling_mode="mean", )
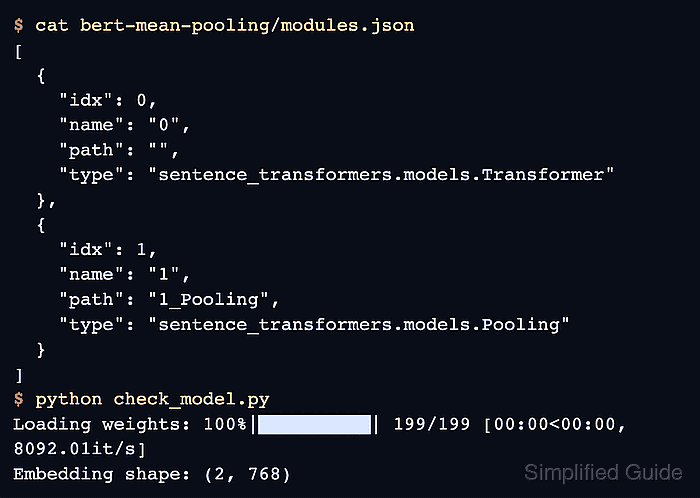
- Display bert-mean-pooling/modules.json to confirm that the Transformer and Pooling modules were saved.
$ cat bert-mean-pooling/modules.json
[
  {
    "idx": 0,
    "name": "0",
    "path": "",
    "type": "sentence_transformers.models.Transformer"
  },
  {
    "idx": 1,
    "name": "1",
    "path": "1_Pooling",
    "type": "sentence_transformers.models.Pooling"
  }
]
Each type line names one saved module. From version 5.4.0, these paths are longer and end in the same two class names. A missing file means the save did not produce the pipeline.
- Create check_model.py in your text editor with a reload and encoding check.
- check_model.py
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("./bert-mean-pooling")
embeddings = model.encode(
    ["A cat is sleeping.", "The train leaves at noon."]
)
print("Embedding shape:", embeddings.shape)
The relative path loads the saved model rather than the original Hub checkpoint.
- Save check_model.py.
- Confirm that the saved model reloads without the original warning and encodes both sentences.
$ python check_model.py
Loading weights: 100%|██████████| 199/199 [00:00<00:00, 8092.01it/s]
Embedding shape: (2, 768)
The two rows correspond to the two input sentences, and each BERT embedding has 768 values. On version 5.3.0 or earlier, the missing “No sentence-transformers model found” line shows that the saved modules.json was used, because a directory without the saved pipeline files logs the warning and prints the same shape. From version 5.4.0, nothing is logged in either case, so modules.json from the earlier step is the proof there. Successful loading and encoding do not establish semantic accuracy for the application.