A service can run on two cluster nodes while its clients still depend on one reachable address. A traffic distribution plan for active-active PCS services defines the client entrypoint, the instances eligible for new requests, and the conditions for removing or returning a node to service.
Pacemaker manages service placement and recovery through resources configured with pcs. A separate load balancer, DNS policy, or routing layer distributes client traffic. Parallel instances must also be safe at the application and storage layers; a clone does not replicate session data or make a single-writer database accept concurrent writes safely.
The surviving nodes need enough capacity for the expected load, and existing connections need time to finish before maintenance. A staging rehearsal can establish whether the chosen health and drain policies behave as intended without interrupting production clients. The HTTP rehearsal uses HAProxy, while the planning decisions also apply to other distribution layers.
Steps to plan traffic distribution for active-active PCS services:
- Identify the service instances available to receive client traffic.
$ sudo pcs status resources
  * Clone Set: web-clone [web]:
    * Started: [ node-01 node-02 ]
The cluster must already have quorum, working fencing, and a service that supports concurrent operation. A Started instance still needs an application readiness check before it receives traffic.
Related: How to create a cloned resource in Pacemaker - Record the client route in the traffic plan.
Decision HTTP planning example Client entrypoint app.internal.example on an internal HTTP listener Backend endpoints 192.0.2.11:8080 and 192.0.2.12:8080 Application protocol Short HTTP requests with a response identifying the serving node TLS boundary Plain HTTP only on the isolated staging network; production requires a documented TLS termination point and certificate owner Client identity Required policy is acceptance of authoritative forwarded client identity only from trusted load balancers For TLS pass-through, backend certificates must match the client-facing name. A proxy using the PROXY protocol needs explicit support at both ends.
- Choose the distribution method for the service protocol.
Method Typical fit Practical failover notes Load balancer HTTP request routing or supported TCP/UDP services Active checks can remove unhealthy backends without waiting for clients to resolve DNS again. DNS round-robin/weighted Clients that can retry other advertised endpoints Resolvers and clients can retain an address beyond its TTL; multiple addresses alone provide no readiness check. Anycast Services with routing control across multiple sites Route withdrawal must follow service health, and a route change can disrupt established connections. The HTTP choice here is HAProxy with equal-weight roundrobin and no session persistence. DNS remains the stable name for its entrypoint. For a DNS address change, the old TTL needs time to expire before cutover.
Tool: DNS TTL Change Window Calculator - Document how clients retain an entrypoint after a load-balancer failure.
A production plan names the redundant load balancers or managed service, address ownership, failure domains, and the mechanism that transfers or withdraws the entrypoint. Two DNS resolvers do not protect a failed service address. A backend drain rehearsal alone does not establish load-balancer redundancy.
Related: How to run an HAProxy failover test in Pacemaker - Reserve enough backend capacity for the agreed node-loss scenario.
For two equally sized nodes, each survivor must handle the whole peak workload within the application's latency and error limits. Illustrative sizing is 600 requests/s at peak and a measured sustainable capacity of 800 requests/s per node, leaving 200 requests/s after one node is lost. The actual plan needs load-test measurements, including shared database or session-store limits.
- Record where session state remains available when a request reaches another node.
Stateless requests or a shared session store allow distribution without affinity. A sticky cookie or source-IP policy may help an application that needs affinity, but it does not preserve state after its chosen node fails. Local uploads, caches, and writes also need an explicit consistency policy.
- Specify an application readiness policy for every backend.
Health decision HTTP policy Request GET /ready with Host: app.internal.example Healthy response Exactly HTTP 200 after required dependencies are usable Check interval 5 seconds Check timeout 2 seconds Removal threshold 2 consecutive failed checks Return threshold 2 consecutive successful checks A listening port or a redirect to a login page does not prove application readiness. An endpoint that always returns 200 can keep a broken instance in rotation.
Startup and dependency recovery times determine suitable thresholds. The interval multiplied by the failure count is an estimate, not a guaranteed client outage bound.
- Define measurable acceptance criteria for the traffic plan.
Scenario Required observation Both nodes ready Both serve new requests under the chosen weights. Planned drain New nonpersistent requests avoid the drained node; its existing sessions finish within the drain budget. Backend becomes unready New traffic avoids it within the removal objective, such as 15 seconds for the HTTP policy. Backend recovers It returns only after the required successful checks. Load-balancer failure The client entrypoint remains reachable within its separate failover objective. Peak load with one node unavailable Error rate and latency remain within application limits. The plan records observed times, errors, and per-node request counts from staging. Round-robin request counts do not imply equal CPU load or equal response times.
- Define the maintenance drain boundary before any cluster action.
The sequence is removal from new-request selection, completion of existing sessions, then node standby or the approved maintenance action. Long-lived WebSocket, streaming, or TCP sessions need a maximum drain time and an agreed interruption policy. HAProxy's drain state can still admit persistent traffic, so the affinity policy matters. Maintenance mode stops Pacemaker management; it does not drain client traffic.
Related: How to run a Pacemaker maintenance window with PCS
Related: How to put a Pacemaker node in standby mode
Related: How to set maintenance mode in Pacemaker - Confirm that both staging backends report readiness.
$ curl -fsS --max-time 5 http://192.0.2.11:8080/ready http://192.0.2.12:8080/ready
ready
ready
The rehearsal starts with an existing staging HAProxy listener for app.internal.example, backend app, servers node-01 and node-02, and the specified readiness thresholds. Its local administrative socket is /run/haproxy/admin.sock. The application responds with its node name at /; a production application's access logs can supply that identity instead. The load-balancer host provides the network perspective for both readiness probes.
- Confirm that the client entrypoint distributes requests to both staging nodes.
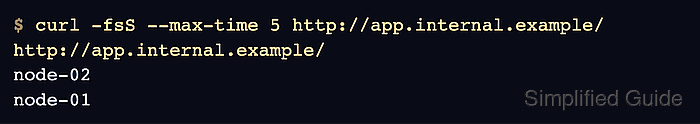
$ curl -fsS --max-time 5 http://app.internal.example/ http://app.internal.example/
node-02
node-01
With equal weights, no persistence, and no competing requests, these two responses should identify different nodes. The order may differ. A nonzero curl exit or an error response means the route needs attention before the drain rehearsal.
- Drain the first staging backend through the HAProxy Runtime API.
This immediately concentrates new nonpersistent traffic on the remaining node. The rehearsal belongs on staging with enough spare capacity and an open administrative session; the ready command below reverses this drain. The socket grants load-balancer administration and must remain local with restricted permissions.
$ printf 'set server app/node-01 state drain\n' | sudo socat stdio UNIX-CONNECT:/run/haproxy/admin.sock
The command addresses one HAProxy process. A redundant pair needs coordinated drain state on every active traffic path, including across reloads.
- Verify that new requests reach the surviving staging node.
$ curl -fsS --max-time 5 http://app.internal.example/ http://app.internal.example/
node-02
node-02
Both responses must come from node-02. This short-request check establishes removal from selection; completion of existing long-lived sessions and the other acceptance-table scenarios need their own staging results.
- Return the drained staging backend to service.
$ printf 'set server app/node-01 state ready\n' | sudo socat stdio UNIX-CONNECT:/run/haproxy/admin.sock
The backend must still pass its health checks before it can receive requests.
- Verify that both staging nodes receive requests again.
$ curl -fsS --max-time 5 http://app.internal.example/ http://app.internal.example/
node-02
node-01
Responses from both nodes show that the planned rotation can remove and return a backend while leaving the service reachable. The plan is ready for production only when its remaining failure, session-drain, and capacity criteria also have passing results.